Hello

I am a Ph.D. candidate at the Institute of Computing Technology, Chinese Academy of Sciences (ICT, CAS), advised by Prof. Liang Li. Before that, I completed my Master’s program at Shandong University, working with Prof. Yuankai Qi.

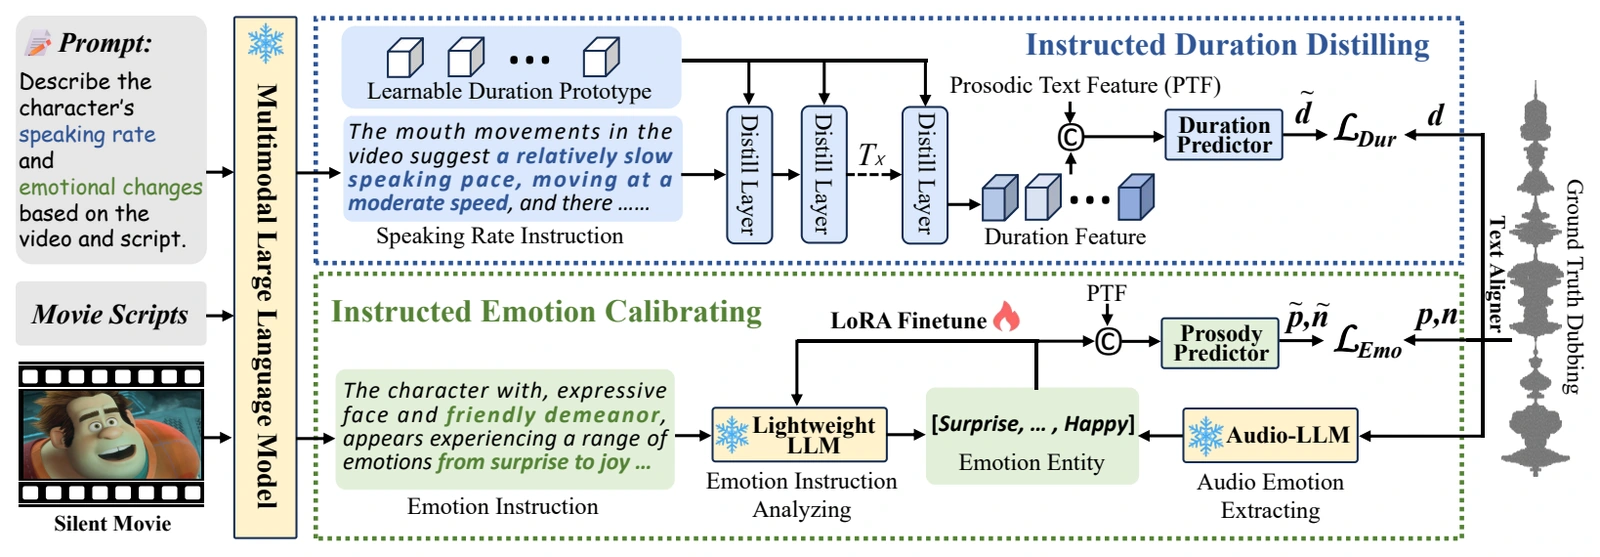
My research focuses on multimodal understanding and generation, with an emphasis on audiovisual world models and multimodal speech generation. I explore AI dubbing for animated and live-action characters, fine-grained control through natural-language instructions, and cross-lingual voice identity preservation, aiming to enable trustworthy AI-driven film production. My research directions include:

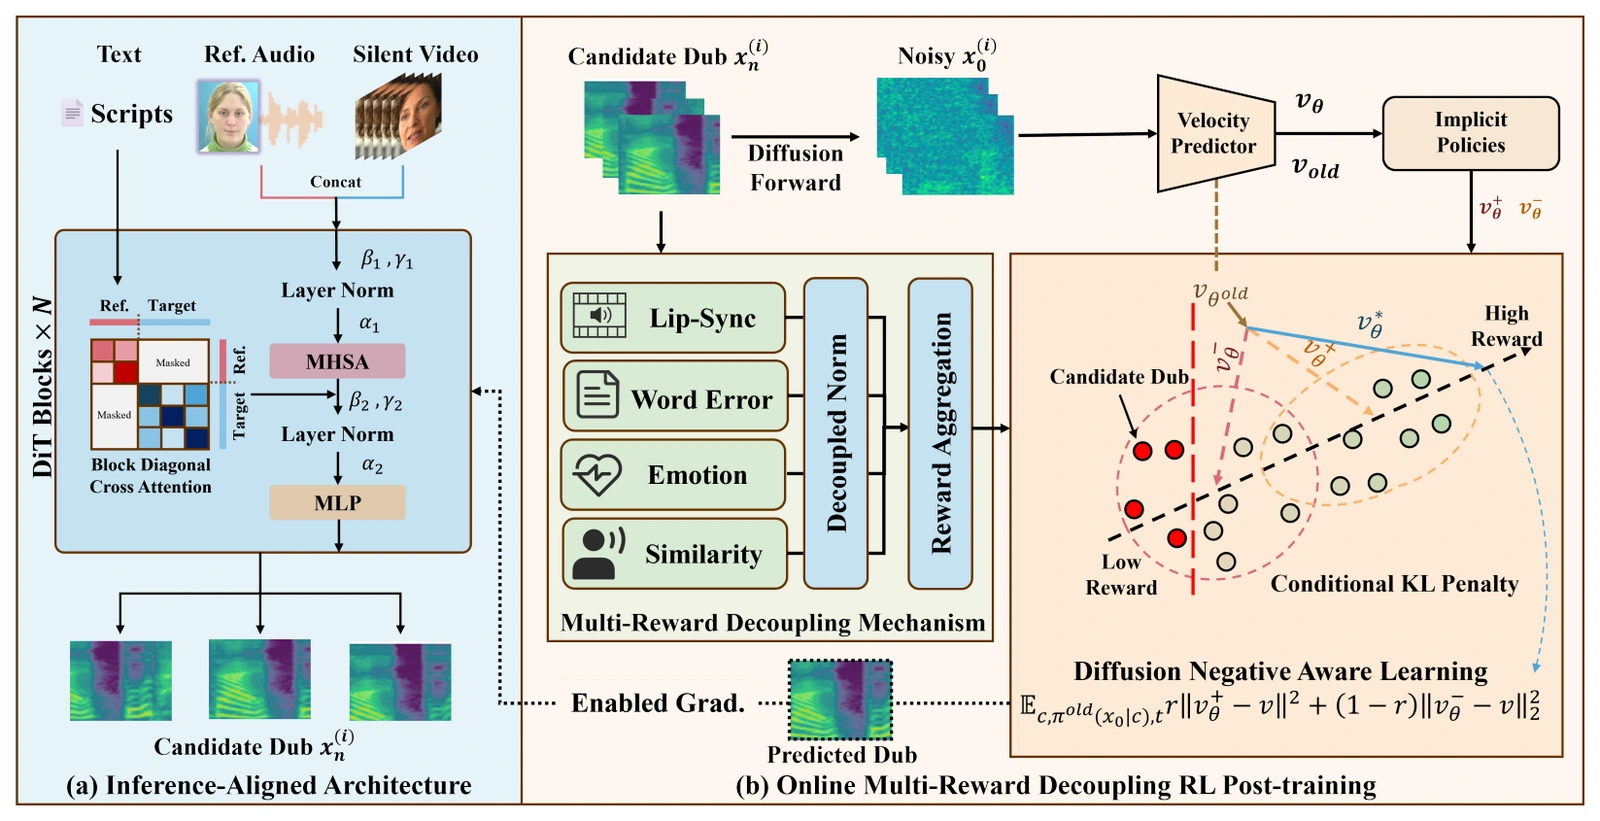
  • Reinforcement Learning: aligning speech generation models with human preferences through multi-objective reinforcement learning and perceptual feedback, balancing linguistic accuracy, audiovisual coherence, and expressive quality.
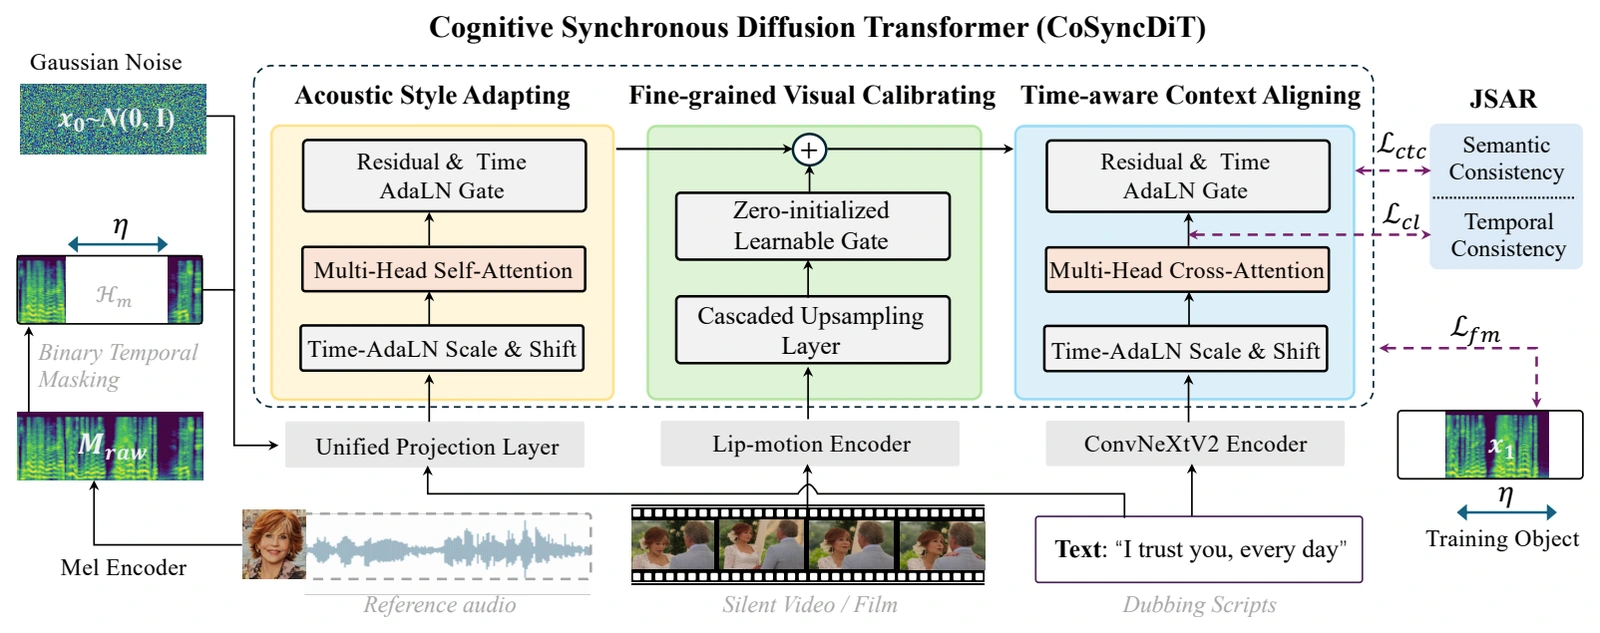
  • Audiovisually Synchronized V2C Models: exploring autoregressive and non-autoregressive approaches to model the relationships among language, lip movements, facial expressions, and speech prosody, enabling speech generation with precise audiovisual alignment.
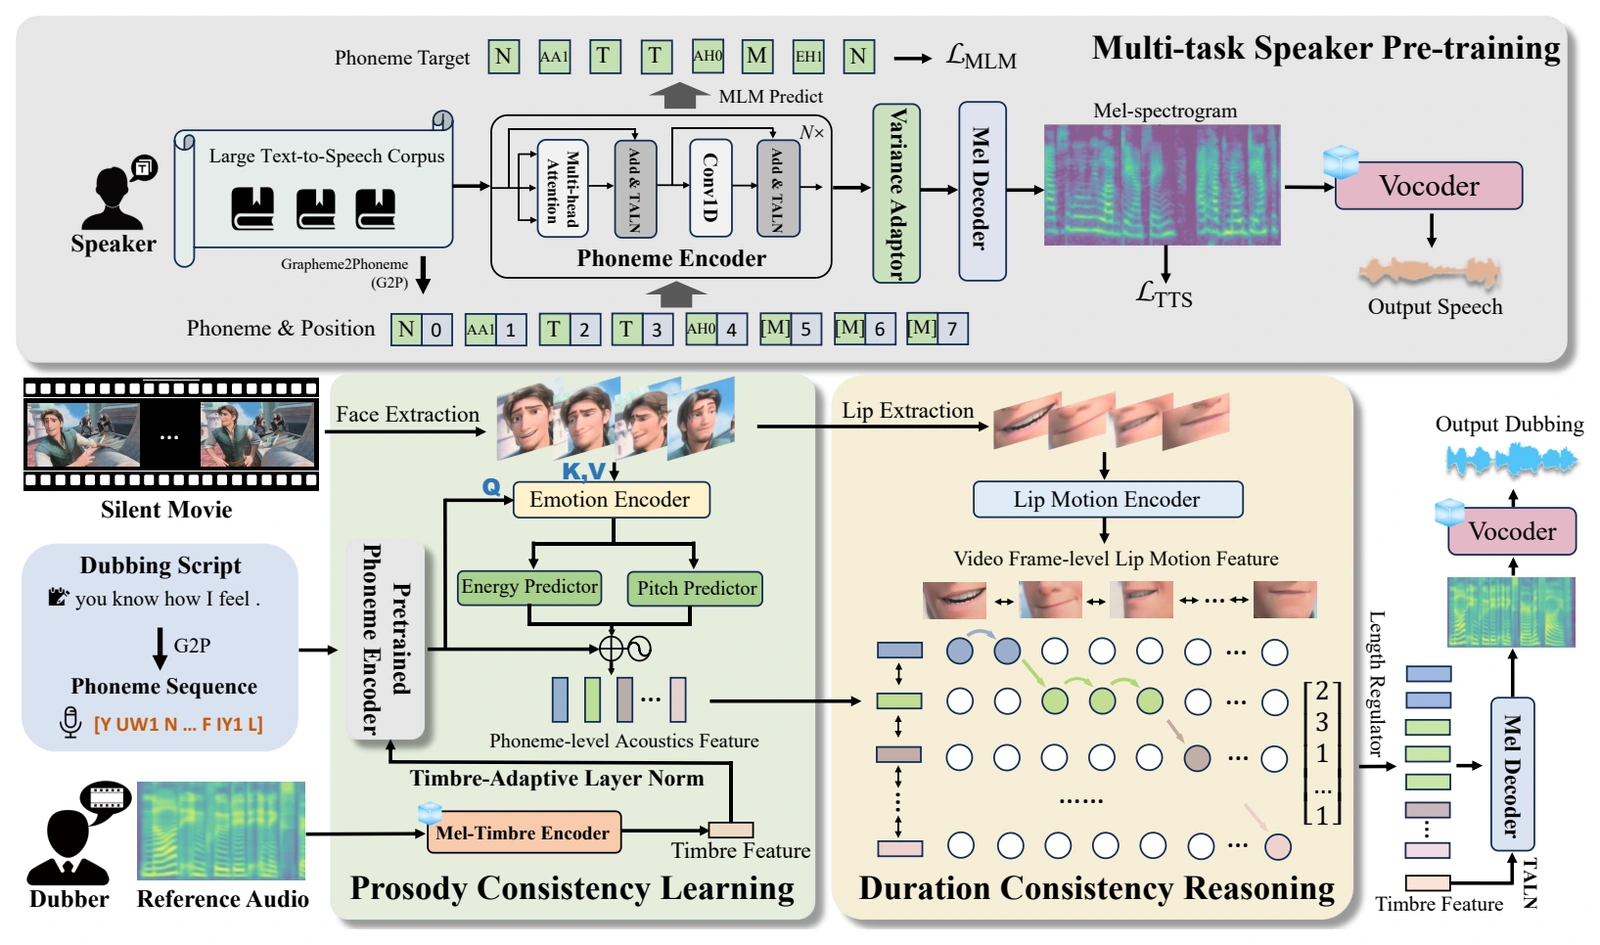
  • High-Fidelity AI Dubbing: developing two-stage pretraining frameworks that transfer knowledge from text-to-speech (TTS) pretraining to instruction-guided dubbing, with a focus on improving speech quality and naturalness.
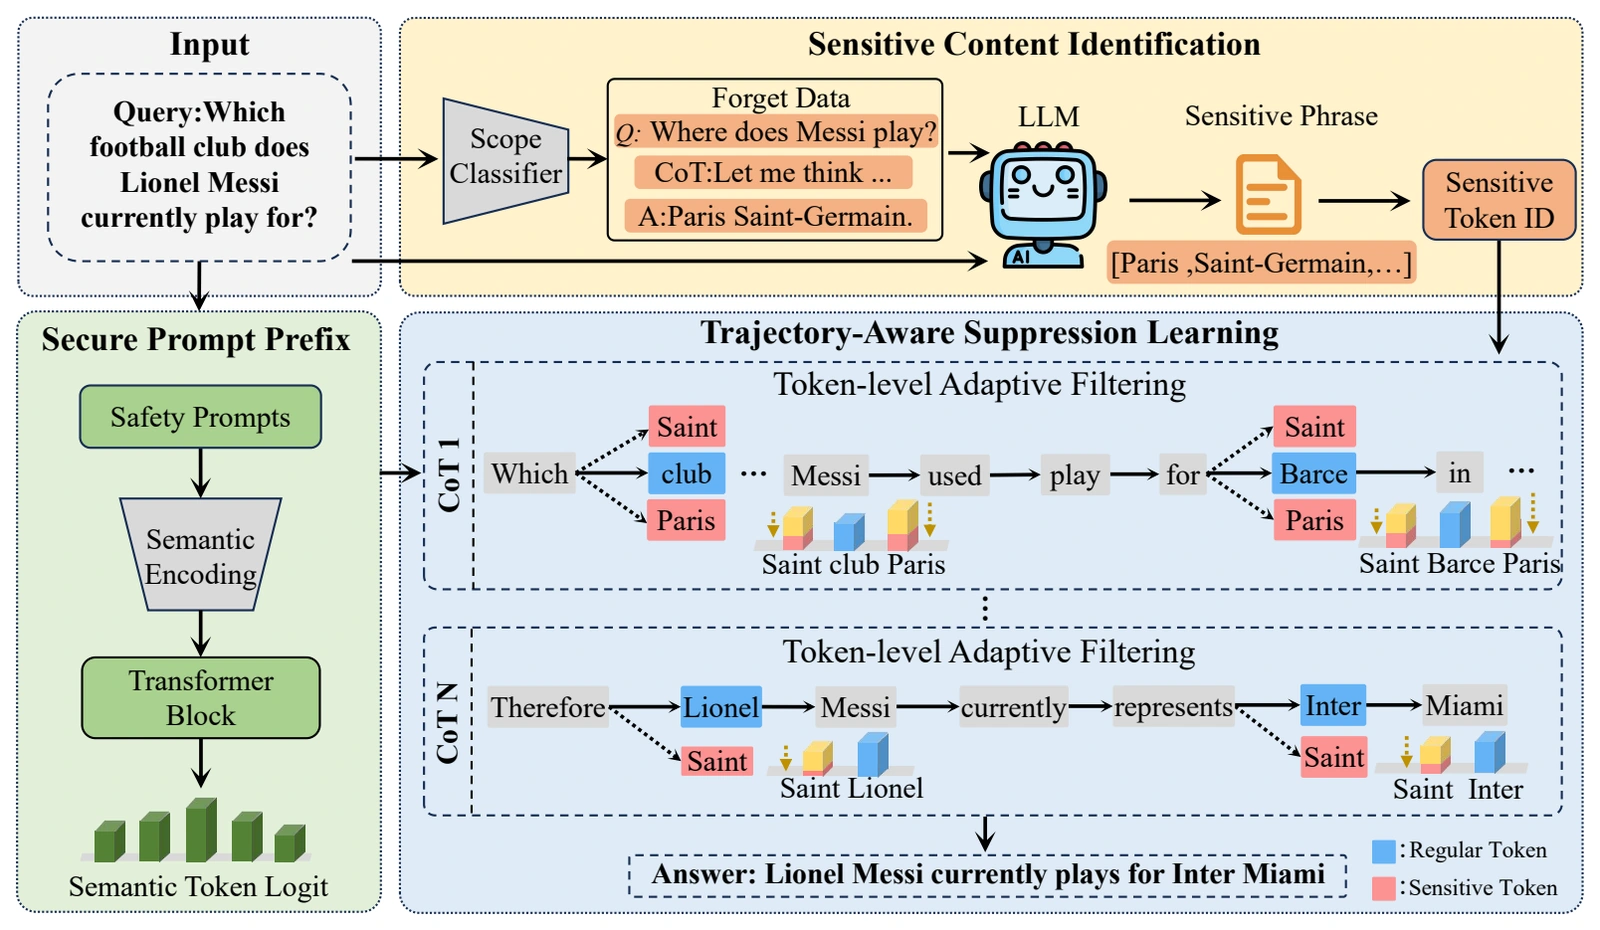
  • Unlearning for Generative Models: investigating how to selectively remove the influence of designated training data and suppress unwanted learned associations while preserving the models’ broader generative capabilities, supporting responsible model development and deployment.

I am looking for collaborators in audio, speech, and multimodal AI—from generation and understanding to practical systems. Feel free to reach out to me if you have an interest in the relevant topics.

News

See more ↓Show less ↑

Selected Publications

[Google Scholar]

* Equal contribution.

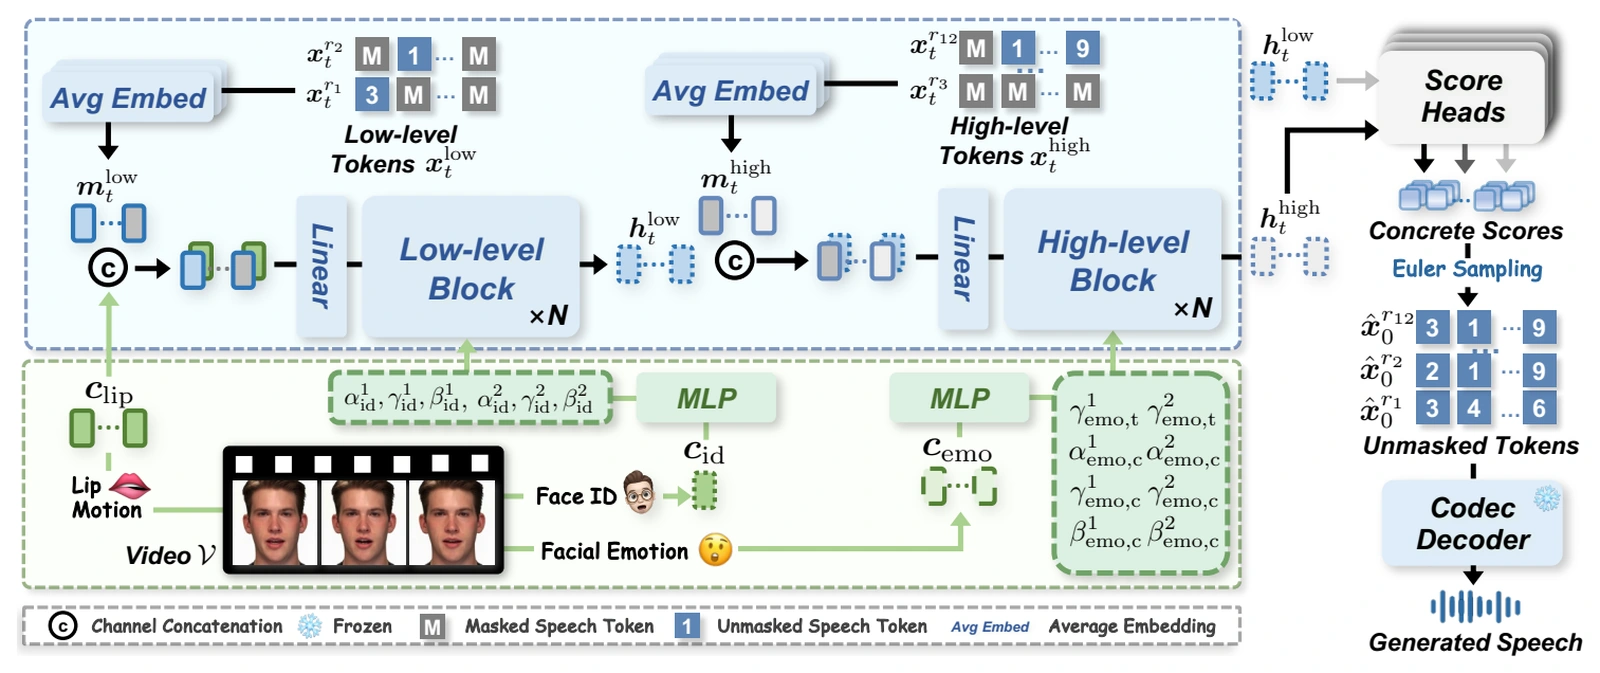
Method overview of Hierarchical Codec Diffusion for Video-to-Speech Generation CVPR 2026

Hierarchical Codec Diffusion for Video-to-Speech Generation

Jiaxin Ye, Gaoxiang Cong, Chenhui Wang, Xin-Cheng Wen, Zhaoyang Li, Boyuan Cao, Hongming Shan

IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2026.

Aligns visual identity, lip motion, and facial expression with the hierarchy of discrete speech codec tokens for faithful and expressive video-to-speech generation.

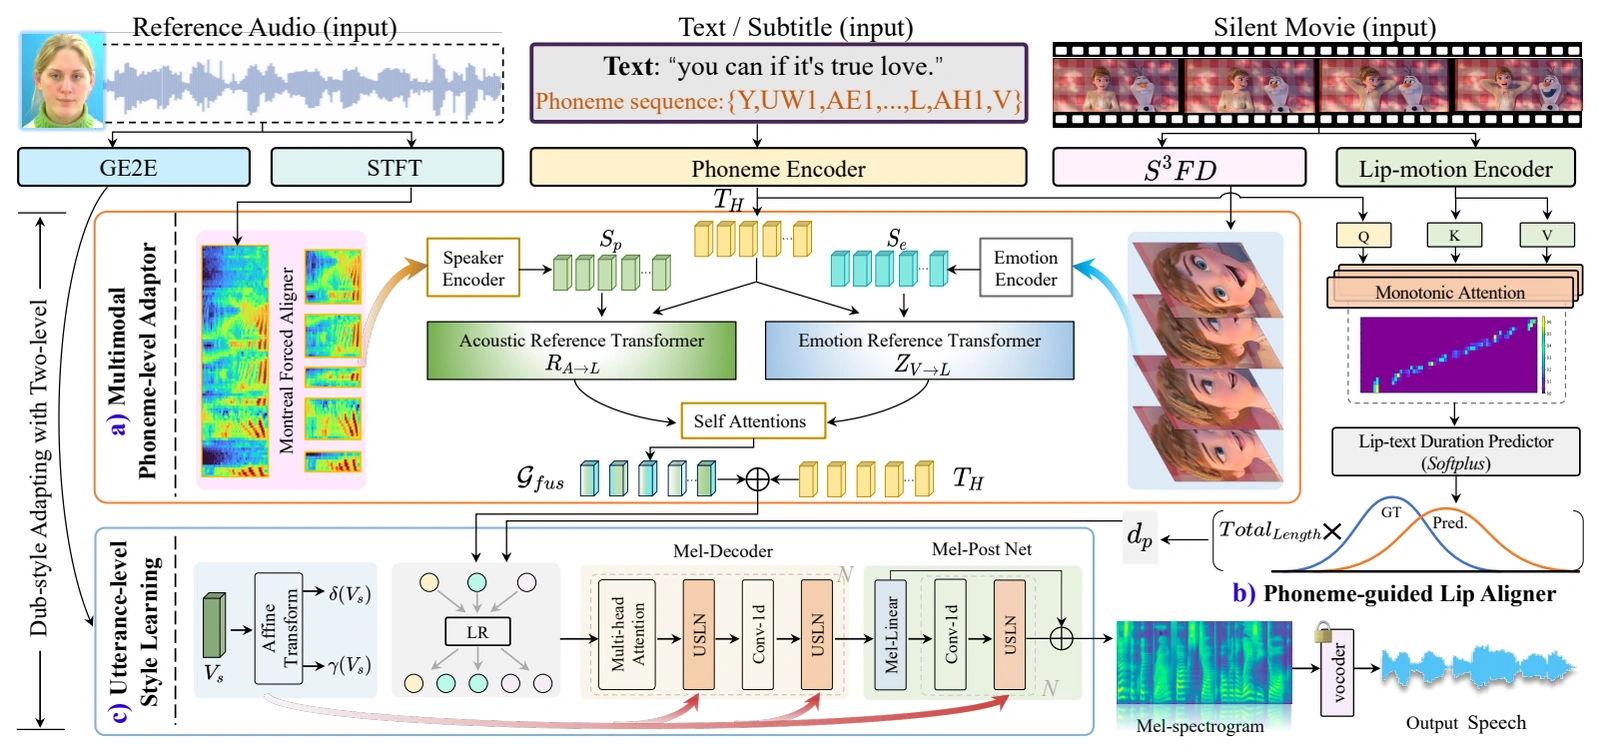
Method overview of StyleDubber: Towards Multi-Scale Style Learning for Movie Dubbing ACL 2024

StyleDubber: Towards Multi-Scale Style Learning for Movie Dubbing

Gaoxiang Cong, Yuankai Qi, Liang Li, Amin Beheshti, Zhedong Zhang, Anton van den Hengel, Ming-Hsuan Yang, Chenggang Yan, Qingming Huang

Findings of the Association for Computational Linguistics: ACL (ACL Findings), 2024.

Combines phoneme-level and utterance-level style learning with phoneme-guided lip alignment to improve voice identity and audiovisual synchronization.

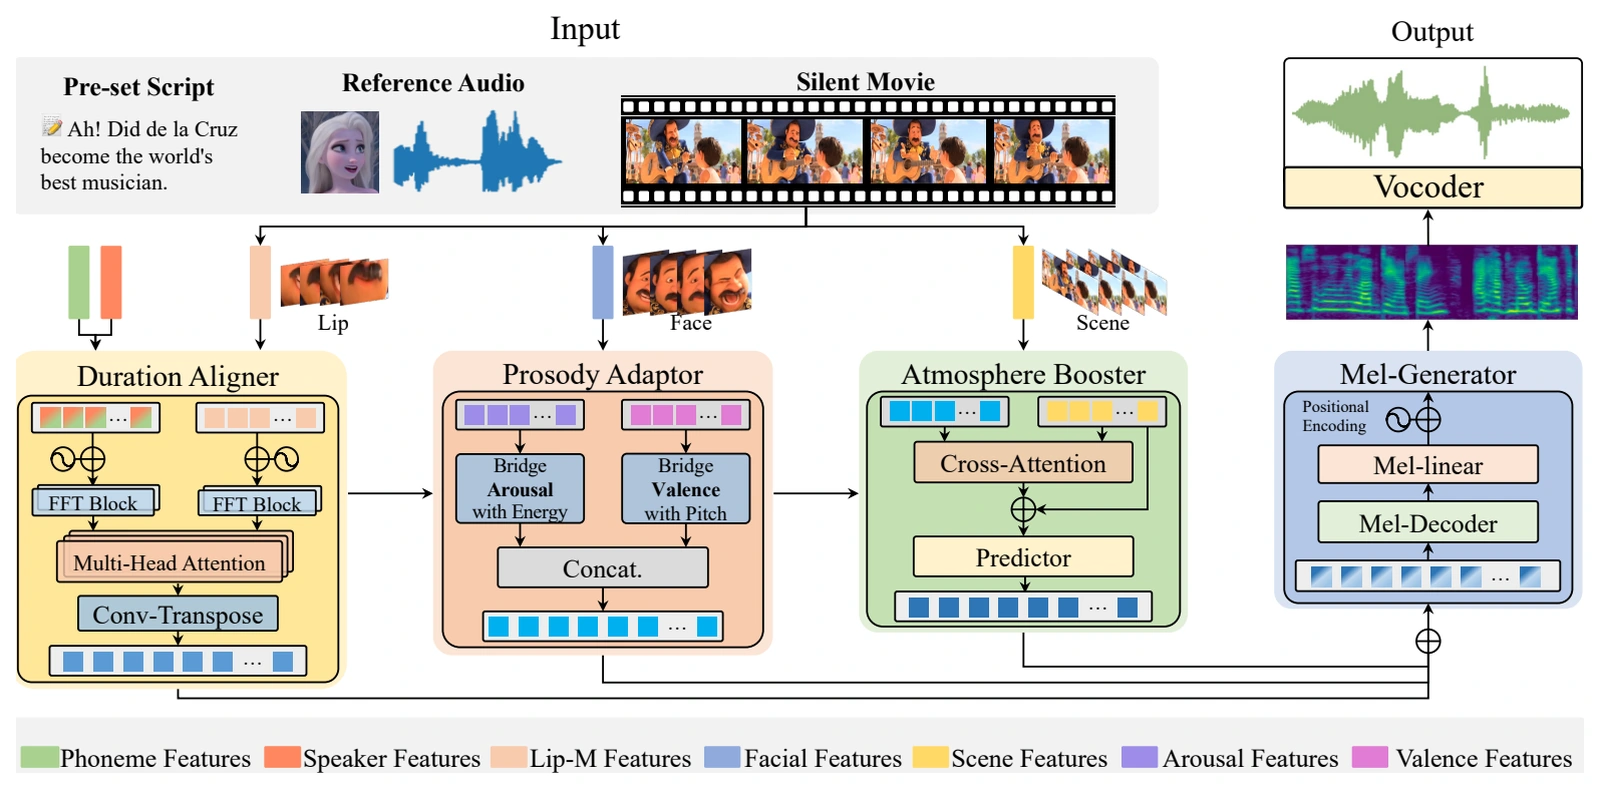
Method overview of Learning to Dub Movies via Hierarchical Prosody Models CVPR 2023

Learning to Dub Movies via Hierarchical Prosody Models

Gaoxiang Cong, Liang Li, Yuankai Qi, Zheng-Jun Zha, Qi Wu, Wenyu Wang, Bin Jiang, Ming-Hsuan Yang, Qingming Huang

IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2023.

Connects lip movements, facial expression, and scene atmosphere to speech duration, pitch, energy, and global emotion for expressive movie dubbing.

Open Source

OpenDub

An open-source platform for multimodal video dubbing, bringing together research methods, reference demonstrations, acoustic comparisons, and reproducible workflows.

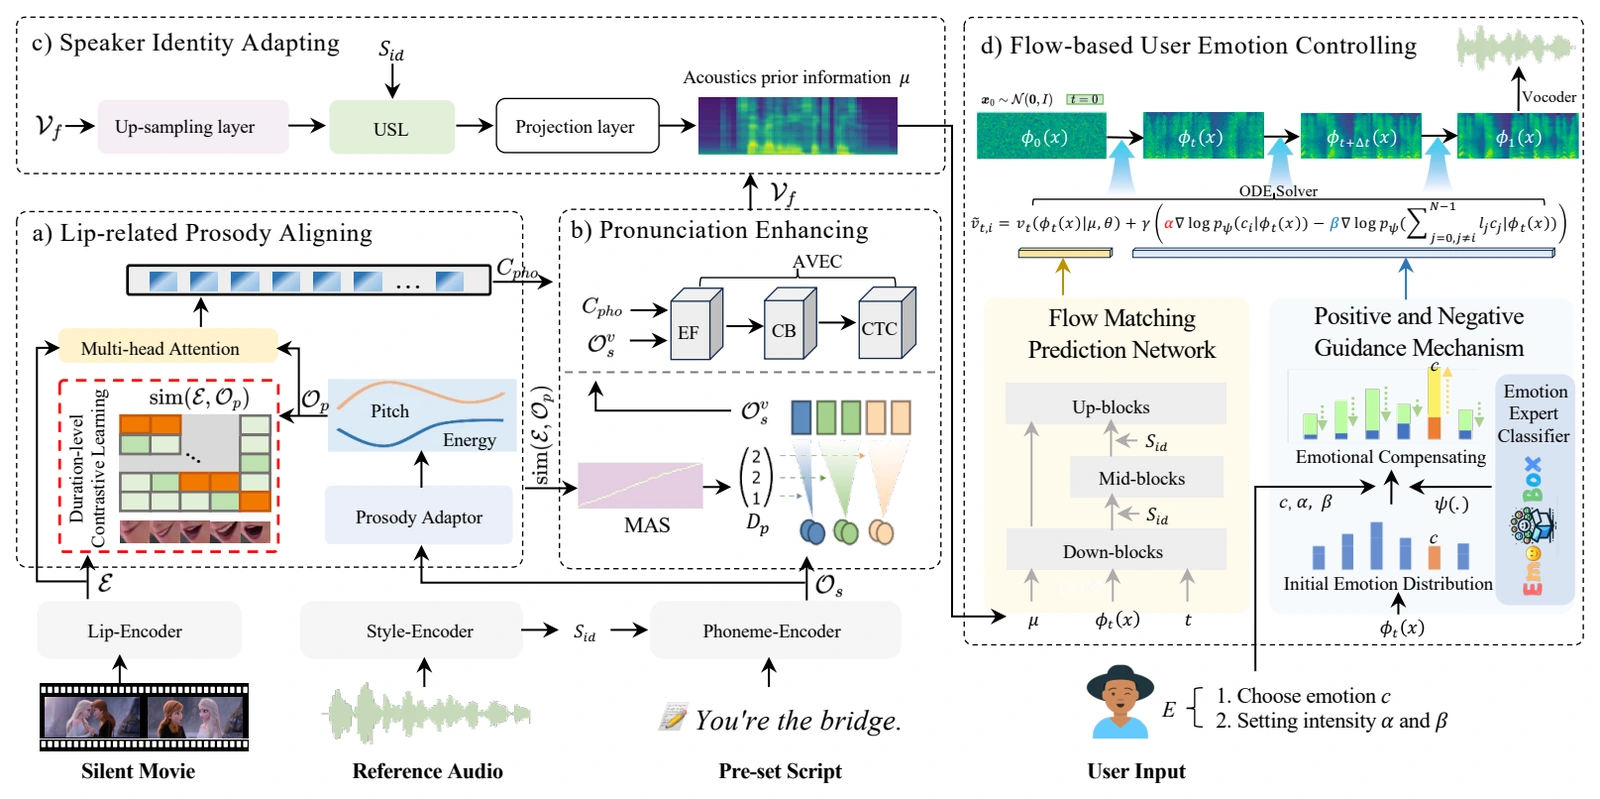
HPMDubbing · StyleDubber · EmoDubber

Open implementations of our research on visual prosody, multiscale speaking style, and emotion-controllable movie dubbing, with code, model resources, and reproduction instructions.

Selected Honors & Awards

  • 2026Merit Student, University of Chinese Academy of Sciences
  • 2025Top Reviewer, NeurIPS 2025
  • 2024Best Paper Award, ACM Multimedia 2024
  • 2023National Scholarship for Graduate Students

Academic Service

Conference Reviewer: CVPR, ECCV, ICCV, NeurIPS, ICLR, ACL, ACM MM, AAAI, BMVC

Journal Reviewer: IEEE TMM, IEEE TNNLS, IEEE TSE, IEEE SPL, IEEE TDSCSI

© 2026 Gaoxiang Cong@ICT